Given an unsorted array of integers nums, return the length of the longest consecutive elements sequence.
Example 1:

Input: nums = [100,4,200,1,3,2]
Output: 4
Explanation: The longest consecutive elements sequence is [1, 2, 3, 4]. Therefore its length is 4.
Playground: Leetcode 128
General Observations
Q. What will be the output if nums contain duplicate numbers (e.g., nums = [1, 0, 1, 2])?
A. The duplicate doesn't increase the sequence length. Hence, we can skip duplicate numbers.
Approach 1: Using Sorting
Sorting the input array will bring all the consecutive elements together. We can then iterate over each element,
incrementing the sequence length if the current element = previous element + 1 or reset the sequence length to
1 otherwise.
Algorithm
1. Sort the array in ascending order.
2. Initialize maxLength to 1 and currLength to 1.
3. Start iterating from the second element to the end of the array.
    4. If the current element = previous element + 1, increment currLength and update maxLength if
    currLength is greater than maxLength.
    5. If the current element != previous element + 1, reset currLength to 1.
6. Return maxLength.
Implementation
Press Play or Step to dry-run the algorithm. The highlighted line is the one currently executing.
Time Complexity
Sorting takes O(n * log n) and the scan pass takes O(n). Hence, the overall complexity is
O(n * log n) + O(n) = O(n * log n).
Space Complexity
Considering we are not using any extra space, the space complexity is O(1).
If the language runtime uses extra stack/temporary memory for sorting, practical space can be higher.
Key Observation
If nums[L] ... nums[R] forms a consecutive sequence, then starting the search from any index i where
L < i ≤ R can only produce a sequence that is shorter than or equal to the sequence starting at L.
In other words, we can say that: "Every element can either be start of a new consecutive sequence or part of an existing one." Exploring a subsequence starting from an element that is already part of an existing
subsequence is redundant, since it will always produce a shorter sequence.
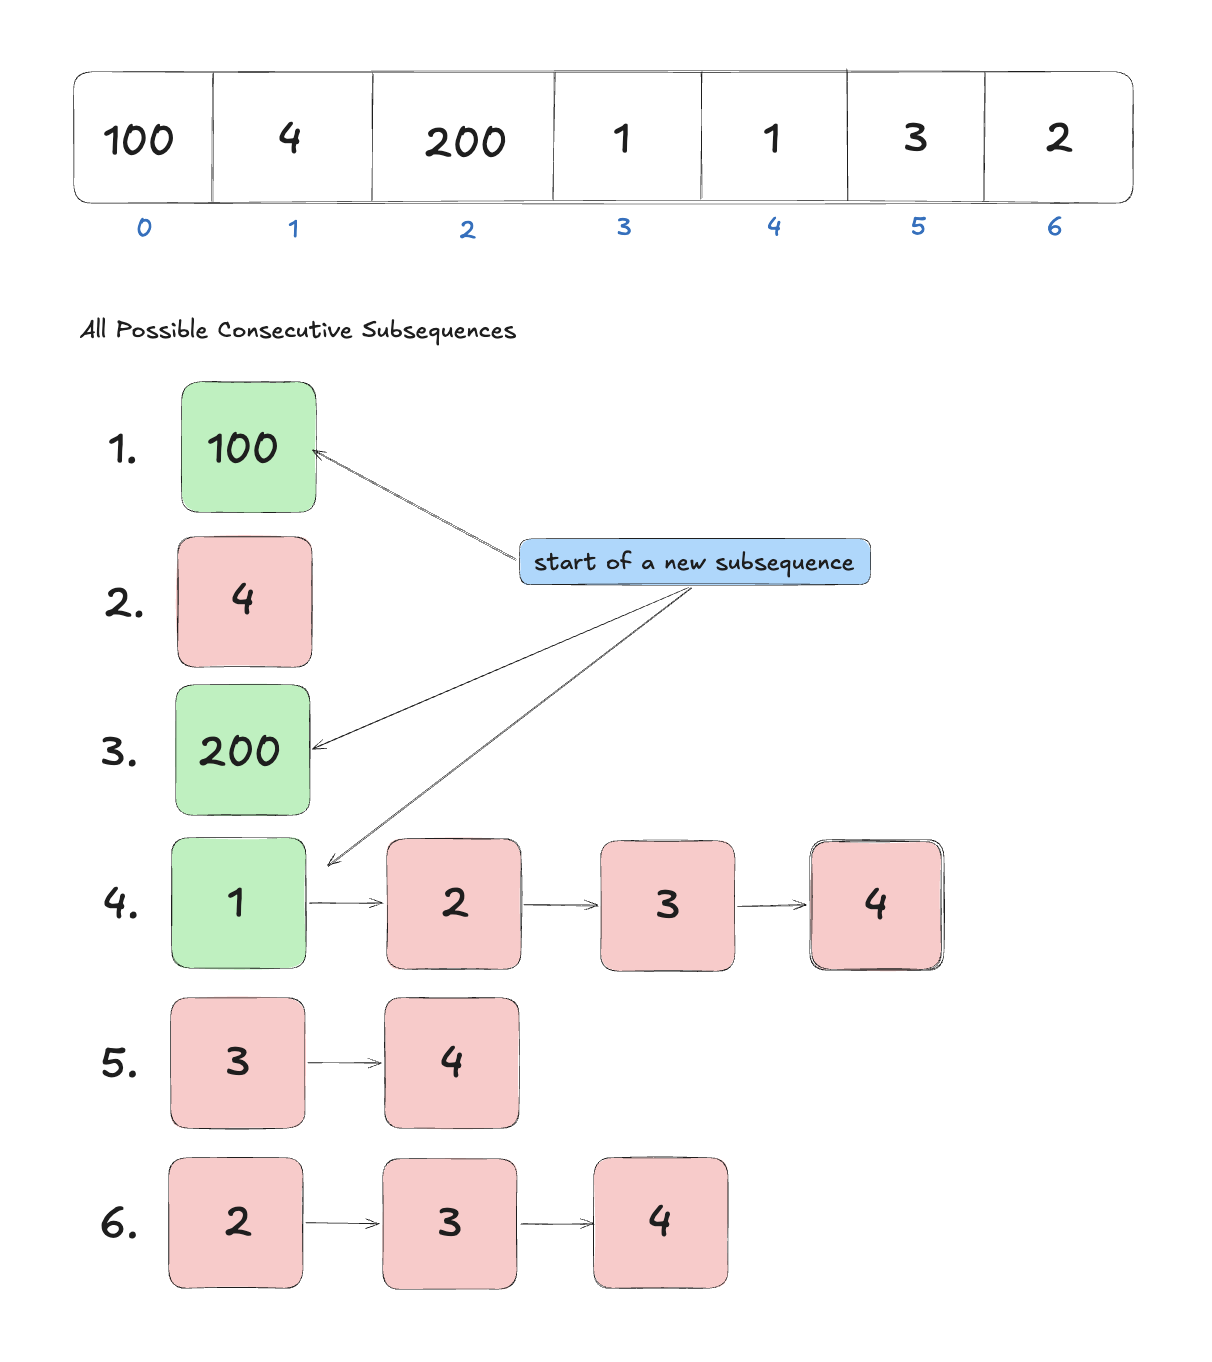
Approach 2: Using Set Data Structure
An element nums[i] marks the start of a new consecutive sequence if (nums[i]-1) does not exist in the input
array nums. In order to efficiently check if (nums[i]-1) exists in nums, we can make use of a set
data structure.
Algorithm
1. Populate the set with all unique elements in the input array.
2. Iterate over the set (to aviod duplicate elements) and for each element, check if it marks the
start of a new consecutive sequence.
    3. If it does, start building the sequence from the current element.
    4. If it doesn't, skip the current element.
5. Return the maximum length of the consecutive sequence.
Implementation
Press Play or Step to build the set and hunt for consecutive runs.
Time Complexity
Building the HashSet processes each input element once, and during expansion, each unique element is visited at
most once. Hence, the overall time complexity is O(n).
Space Complexity
In the worst case (no duplicates), we store all n elements in the set. Hence, the overall space complexity is
O(n).